Doing It Right with FiftyOne: Sim-to-Real Gesture Classification for Human-Robot Interaction
by John Duncan
• 16 min read
Author
Machine Learning Engineer
I'm a customer success machine learning engineer here at Voxel51, where I work with our enterprise customers to implement their ML workflows in FiftyOne. I earned my Ph.D. in Robotics from UT-Austin, where I specialized in multimodal perception for command and control of robots in dynamic, unstructured environments.
See all articles by John Duncan
In this article
Why gesture classification for human-robot interaction?Step 1: Loading the RoCoG-v2 dataStep 2: Adding pose prelabels and embeddingsStep 3: Classifying the gesture video clipsStep 4: Temporal classification with a causal model you can deployStep 5: Model training and evaluationStep 6: Zero-shot evaluation on in-the-wild robot dataWhat actually closed the sim-to-real gapReferencesAppendix: YOLO-pose prelabeling code snippetsQuestions? We have answers.
In this article
Why gesture classification for human-robot interaction?Step 1: Loading the RoCoG-v2 dataStep 2: Adding pose prelabels and embeddingsStep 3: Classifying the gesture video clipsStep 4: Temporal classification with a causal model you can deployStep 5: Model training and evaluationStep 6: Zero-shot evaluation on in-the-wild robot dataWhat actually closed the sim-to-real gapReferencesAppendix: YOLO-pose prelabeling code snippetsQuestions? We have answers.
Try Voxel51 for yourself
In 2024 I trained a gesture classifier for human-robot interaction. It scored 24% accuracy, only a hair above the 14.3% chance floor. It lived in a Jupyter notebook so disorganized that I couldn't tell you why the model was bad. I rebuilt it in FiftyOne. It now scores 51.3% on 840 clips of my own robot footage that it never trained on, against a 2024 number that included that footage in training.
This isn’t a story about building models, though. Model architecture changes barely moved the needle. Everything that did was a data problem I could only see once the data was somewhere I could look at it.
This isn’t a story about building models, though. Model architecture changes barely moved the needle. Everything that did was a data problem I could only see once the data was somewhere I could look at it.
Some key takeaways from this project:
- ~200 real clips beat ~2,000 synthetic ones. On real robot test footage, a gesture classifier trained on 204 real clips scores .760 accuracy against .590 for one trained on 1,980 synthetic clips. In-domain data gets in-domain performance.
- Data changes moved the needle, model architecture did not. In this sim-to-real gesture classifier, pose normalization added +.17, windowing added +.17, real training data added +.17, and longer windows added +.069. Swapping LSTM for a temporal convolutional network was worth +.005, less than the .017 spread from re-running one model at a different random seed.
- The sim-to-real gap is not one gap, it is five. This project found feature-space separation, apparent person scale, a labeling convention mismatch between two annotating teams (roughly 40% of the apparent gap), the pose estimator's perspective sensitivity, and a residual 14-point performance gap.
- Aggregate classification metrics hide per-class nuance. There is no "51% accurate gesture model" here. Three gestures are essentially solved, three sit at or below the 14.3% chance floor, and the same bimodality shows up in Steps 3 and 5.
- Zero-shot on in-the-wild robot footage more than doubled. The rebuilt classifier scores 51.3% on 840 clips of the author's own robot footage it never trained on, against 24% in the 2024 version that had that footage in its training set.
Why gesture classification for human-robot interaction?
As robots are continuing to operate with and among humans, the need for robots to accurately recognize human intent is more important than ever. But the catch is that the typical pedestrian doesn’t carry a robot controller–so a robot in the wild must perceive humans using only onboard robot sensors (exteroception).
HRI in the wild is a real challenge which I explored as part of my dissertation research. The gesture recognition model was a key part of the exteroceptive system I built. But the implementation itself wasn’t very robust: an LSTM implemented in a Jupyter notebook I got from a labmate, trained on synthetic and real data from the Robot Control Gestures (RoCoG v2) dataset, plus a dataset that I recorded on my actual robot.
Both RoCoG and my dataset used the same, standard set of hand and arm signals:
When I submitted it for publication, the reviewers understandably noticed that the gesture classifier and the overall experiments needed improvement. To paraphrase:
- …gesture classification results are around random chance level…
- Does gesture recognition accuracy improve in different scenes?
Worse yet, the experiment notebook was so disorganized that I had no idea why the model was performing poorly.
Fast forward to today: I have access to Voxel51 (perks of the job!) and can perform a more rigorous inspection at each stage model development.
Step 1: Loading the RoCoG-v2 data
I used the RoCoG v2 dataset for the gesture classifier, a set of 7 standard hand & arm signals. The dataset is free, available online, and includes over 100k annotated videos across synthetic, real, aerial, and ground operating domains. The authors include nominal train, val, and test splits.
Loading the samples into FiftyOne is straightforward (video samples are natively supported) and the gesture labels are applied to each video as
fiftyone.Classifications. I added a domain field to specify the source of the data (synthetic-ground / synthetic-air / real-ground / real-air). The authors also included train/val/test designators, which I include in the split field.This is a large dataset, so I stored it in my cloud bucket and served it using Voxel51’s native cloud support.
From there, taking inventory of the data and managing splits was just a few clicks in the sidebar.
One quick note: I only used about 5% of the synthetic data, taken by randomly sampling the full synthetic split with the
Take method. Specifically, I took 4820 synthetic clips (exactly 10x the 482 real clips), for a total of 4820 synth + 482 real = 5302 clips. The 5302 clips span the entire domain and class strata. The smaller dataset keeps things tractable for the compute-heavy operations that come next.In total, the samples in my dataset are distributed as follows:
| Domain | Train | Val | Test | All |
|---|---|---|---|---|
| synthetic-ground | 1933*(1980) | 415*(413) | - | 2408 |
| synthetic-air | 2000 | 412 | - | 2412 |
| synthetic (total) | 3993 | 827 | - | 4820 |
| real-ground | 204 | - | 100 | 304 |
| real-air | 87 | - | 901 | 178 |
| real (total) | 291 | - | 191 | 482 |
| all | 4284 | 827 | 191 | 5302 |
There are a total of four domains (synthetic-ground, synthetic-air, real-ground, real-air); synthetic data has train and val splits, while real data has train and test splits. I only train and evaluate on ground samples for the causal model, so data are ground unless specified otherwise.
*On top of that, some of the synthetic-ground clips were missing but still contained ground truth data; so technically, only 1980 are used for training and 413 for validation.
*On top of that, some of the synthetic-ground clips were missing but still contained ground truth data; so technically, only 1980 are used for training and 413 for validation.
This is getting a little complicated so I’d like to clarify the naming convention I use from here on out:
| Split name used in this paper | Split name used by RoCoG authors | Number of ground clips |
|---|---|---|
| sim-train | synthetic (train) | 1980 |
| sim-val | synthetic (val) | 413 |
| real-train | real (train) | 204 |
| real-test | real (test) | 100 |
All splits are ground-only unless explicitly stated otherwise. Absolutely everything after step 4 is ground only.
Step 2: Adding pose prelabels and embeddings
Right away there’s a pretty big issue. I have plenty of video clips, but my LSTM architecture doesn’t operate on pixels–it needs pose features, and everything downstream depends on them.
I applied YOLO11-pose to all 5302 videos using a custom FiftyOne SDK Python script. The pose keypoints are applied as
fiftyone.Keypoints annotations, with the skeleton schema added as a fiftyone.KeypointSkeleton to graphically depict the skeletal poses on each video. Code snippets are provided in the Appendix below.Next, as a sanity check I computed visual embeddings for 977 clips and pose keypoint embeddings for 566 clips so that I could inspect them in FiftyOne’s embeddings panel. The embeddings panel is a great tool to quickly identify clusters and outliers.
Embeddings space of the gesture features.
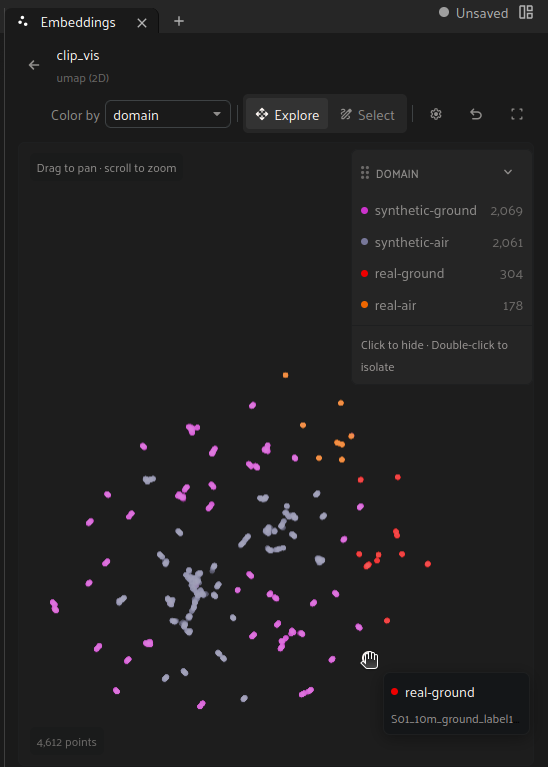
Qualitatively, we can see that the real samples occupy one small area of the vector space, and the synthetic samples span a much larger vector space. The intersection of these two vector spaces appears pretty minimal. This is true for both the visual features and the pose-keypoint features.
For example, there is this real aerial sample in which the terrain kind of looks like the synthetic ground terrain:
Exploring the embeddings panel to find a real aerial clip whose grassy terrain resembles the synthetic ground clips surrounding it.
It’s not definitive proof of anything at this point, but it is another indicator of what we already know: the sim and real visuals and gestures are largely distinct. Does this matter for model performance? We’ll find out.
Step 2.5: Normalizing the pose features
At this point, I actually ran a preliminary gesture classifier, which scored 44% accuracy on sim-val.
But this also surfaced another key issue: variance in skeletal pose sizes. The pose keypoints and joints get normalized to the image frame size. Camera distance and body orientation can vary the apparent skeleton scale by up to 2.8× across the ground clips. A torso turned to the side shortens the shoulders exactly like extra distance does.
To address this, I normalized the features to the skeleton itself; you can move the hip to the origin, and scale all the lengths by the shoulder width. camera distance and body orientation together.
This normalization step yielded the single largest performance improvement in this project--44% to 61% on the sim validation split--and I’ll discuss it in the next section. In any event, we have consistent features! Now, time to really train the classifier.
Step 3: Classifying the gesture video clips
The first ML task for the dataset, and the one I previously explored, is classifying the gesture clips.
To accomplish this, I used the FiftyOne Python SDK to train a Long Short-Term Memory (LSTM) model on the RoCoG's synthetic training clips (ground + aerial, n=3980), then evaluated it on sim-val and real-test splits. The end goal is to optimize model accuracy on the ground samples in the real-test split, since that’s the domain I’m targeting for my robot.
The LSTM is applied bidirectionally to each frame’s skeletal pose keypoint features for each video, generating an estimate and confidence for each frame. I took the non-background maximum confidence gesture to be the clip’s overall classification, and saved the class and confidence as a
fiftyone.Classification.FiftyOne’s model evaluation panel (MEP) makes it easy to get a rundown of how the clip classifier works on the ground real-test:
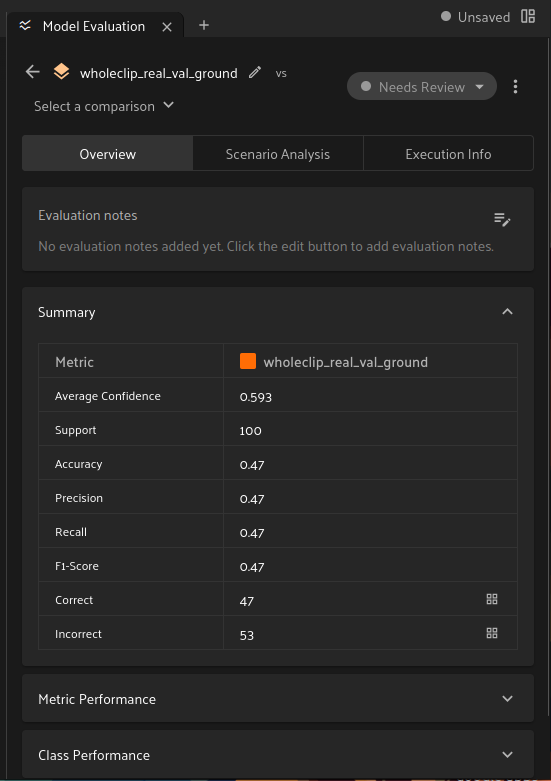
The key performance numbers here are 47% accuracy and 39% macro F1 for the LSTM on the ground real-test split. There’s also an interesting breakdown here which we can see using the Class Performance tab:
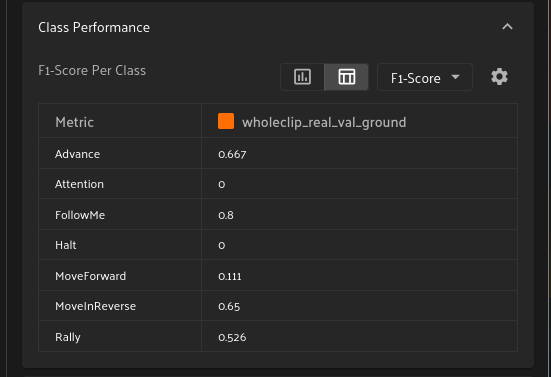
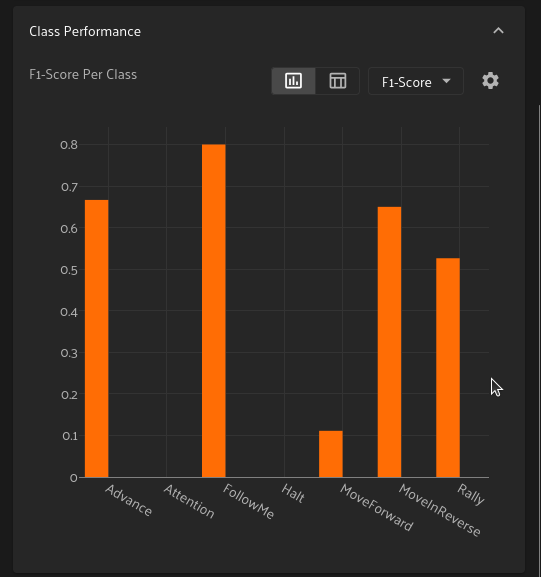
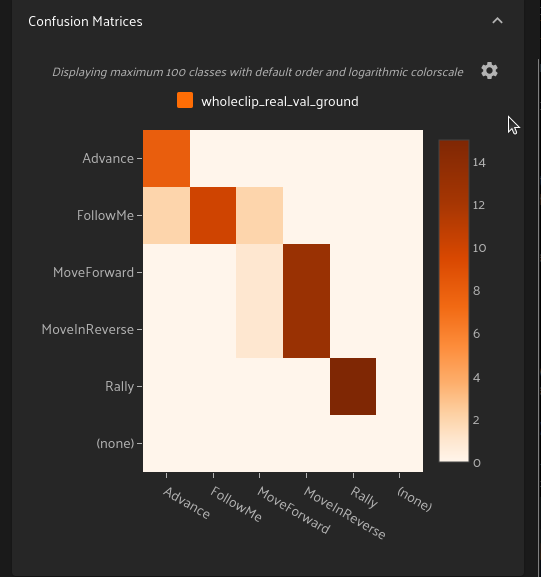
- Advance, FollowMe, MoveInReverse, and Rally all have F1 scores above .5
- Attention, Halt, and MoveForward have F1 scores at or below ~.1
And for completeness, here is how the LSTM performed on different evaluation splits:
| Scope | Eval split | Clips | Accuracy | F1 |
|---|---|---|---|---|
| grounds+aerial | sim-val | 827 | .594 | .565 |
| ground+aerial | real-test | 191 | .461 | .378 |
| ground | sim-val | 413 | .608 | .584 |
| ground | real-test | 100 | .470 | .393 |
What this tells us
The classifier has 47% accuracy on real clips the model has never seen, against a 14.3% chance floor. The model was trained only on synthetic data, so this is a proper transfer, not overfitting the training data. It also loses about 14 points of accuracy going from synthetic to real.
But the average is misleading: four gestures clear 0.5 F1 and three are near-zero. This isn’t a "47% model", rather it’s a model that knows four gestures well and doesn't know three.
This step also exposed a subtle presentation of the sim-to-real gap: differences in pose conventions between real and synthetic data.
Step 4: Temporal classification with a causal model you can deploy
The clip classifier answers what the gesture is, but the robot also needs to estimate when a gesture occurs. It never receives a tidy .mp4, it receives sequential frames, and has to buffer them to decide on what it has seen so far. So the model has to be causal: a trailing window input, a gesture and a confidence out.
As with any supervised learning task, we need labeled training data for this. But there’s a key limitation of the existing dataset: there are no temporal labels on the real data. We’ll have to use the existing class labels and devise a way to identify the timeframe when the gesture occurs.
FiftyOne’s
fiftyone.TemporalDetection label type is designed for exactly this scenario--capturing a class and the temporal duration. With the recent improvements to video annotation, it’s straightforward to view, add, and modify the temporal labels directly in the app.Editing a TemporalDetection label in the FiftyOne app, setting the start frame, stop frame, and Advance gesture label on a robot clip.
What followed was a discovery phase that involved lots of trial and error. The key tools here were the FiftyOne visualization, annotation, tags & views to manage data splits, and the Python SDK to run Torch model training and inference. The key underlying pattern was differences in how samples were labeled:
- Gestures in the synthetic samples start partway through the clip. The beginning and end frames are specified in a separate metadata file.
- Gestures in the real samples also start partway through the clip. However, the beginning and end frames aren’t specified, only the overall label.
The initial causal models performed poorly because the video frames were using different ground truth labeling conventions. Effectively, the model was learning one temporal window and attempting to classify another. In this case, the differences in labeling conventions and data format accounted for about 40% of the model’s discrepancy on the sim-val split. Fixing the convention brings the sim data in line with the real data and narrowed the gap significantly.
Finding a common representation
Knowing that I have different ground truth conventions in play, any downstream training or evaluation tasks will be useless unless I can apply a unified temporal labeling convention across my data.
I needed something that can be quickly applied to synthetic or real data, from the RoCoG dataset or other sources. So I devised a simple rule-based scheme:
- The gesture begins when the wrist keypoint goes above the elbow keypoint for the first time in the clip (minus a learned offset*)
- The gesture ends when the wrist keypoint goes below the elbow keypoint for the last time in the clip (plus a learned offset*)
*For most gestures the offset is minimal ( < .15 seconds), indicating that the offset isn’t really needed – the rules work well on their own.
Gestures in the dataset clips are very conspicuous, and we can exploit this knowledge--no one raises their hand above their elbow unless a gesture happens. This rules out false positives from people swinging their arms while swaying in the real splits.
After the correction, all the RoCoG data has a shorter, more consistent segment of the video annotated.
Quick note: I excluded aerial samples for further analysis, because the rule above breaks down on aerial samples. Even after normalizing the pose keypoints to align along the skeletal torso axis instead of the aerial video frame axis, there is apparent shortening of the forearms by about 25%. Because I’m using this rule to add ground truth labels, I made the choice to exclude the aerial split. The ultimate goal here is a gesture classifier for a ground robot, so this seemed prudent to keep the rest of the project scoped and tractable.
To validate the automated rule-based approach, I annotated a validation subset of the real and synthetic samples. The rule-based approach had a .970 median IoU against my hand-annotated samples, and a .734 IoU against the full synthetic window with clearly defined lead and trail buffers. So there is excellent overlap between the rule and my hand-annotated samples; the rule can consistently and realistically extract the window when the gesture is happening, so I’ll use it to apply the ground truth temporal windows on the samples.
And for bookkeeping purposes, I added a gt_source field to ensure that the original RoCoG TemporalDetections didn’t get mixed and matched against my own rule-based TemporalDetections.
To conclude: we now have consistent ground truth labels and gesture convention across the entire RoCoG dataset. This came after identifying a difference in how the synthetic and real sample ground truth windows were labeled, and replacing both with a rule-based approach which matched my hand-annotated method.
With ample training data in hand, I can move on to model training and evaluation.
Step 5: Model training and evaluation
I trained and evaluated two model architectures: LSTM and Temporal Convolutional Network (TCN), both commonly used for classifying short temporal sequences. Since both can accommodate an arbitrarily long input sequence, I used windows of .5, 1.0, and 2.0 seconds.
I used the FiftyOne Python SDK to select the relevant training and eval splits, and then train the LSTM and TCN implementations in PyTorch. I then applied the trained model back onto my FiftyOne samples using the
apply_model() function.I can also evaluate them natively within FiftyOne, again using the evaluation module. For temporal detections on video clips, FiftyOne supports ActivityNet-style evaluation. ActivityNet compares the classwise predictions as well as the IoU of the ground truth and predicted
TemporalDetection windows.| Model | Training set | Accuracy: sim-val (413) | Accuracy: real-test (100) | sim-> real gap |
|---|---|---|---|---|
| LSTM, whole clip (Step 3) | synthetic | .608 | .470 | + .138 |
| LSTM, 2s window | synthetic | .964 | .640 | + .324 |
| LSTM, 2s window | synthetic+real | .949 | .810 | + .139 |
| TCN, 2s window | synthetic | .944 | .590 | + .354 |
| TCN, 2s window | synthetic+real | .944 | .820 | + .124 |
| TCN, 2s window | real | .237 | .760 | - .523 |
And macro F1:
| Model | Training set | F1: sim-val (413) | F1: real-test (100) | sim-> real gap |
|---|---|---|---|---|
| LSTM, whole clip (Step 3) | synthetic | .584 | .393 | + .191 |
| LSTM, 2s window | synthetic | .964 | .615 | + .349 |
| LSTM, 2s window | synthetic+real | .949 | .813 | + .136 |
| TCN, 2s window | synthetic | .945 | .540 | + .405 |
| TCN, 2s window | synthetic+real | .944 | .817 | + .127 |
| TCN, 2s window | real | .224 | .743 | - .519 |
And here’s the per-gesture model F1 on real-test for different training sets:
And lastly, the mAP table which shows temporal localization performance by training and eval sets:
| Training set | sim-val (413) | real-test (100) |
|---|---|---|
| synthetic (TCN) | .3603 | .1497 |
| synthetic (LSTM) | .3826 | .1712 |
| synthetic+real (TCN) | [not run]* | .2542 |
| real only (TCN) | [not run]* | .2517 |
*mAP values cannot be computed if there are no valid temporal predictions.
There are some key takeaways here:
- Adding real data to the training set gives a minor degradation to the synthetic evaluation metrics, but a ~20 point improvement to eval metrics on the real dataset
- The bottom row reveals an asymmetry between sim and real data: training on 204 real clips transfers to real and not at all to synthetic; training on 1,980 synthetic clips transfers partway to both.
- Window length is the most important model parameter. Across both LSTM and TCN architectures, accuracy improves monotonically by ~7 percentage points as the temporal window length is extended from 0.5 to 2.0 seconds.
- Model architecture is significantly less important; accuracy varies by about .005 between different model architectures, less than the ~.017 variance from choosing a different random seed.
- When trained on synthetic+real, the TCN (2.0s window) model’s clip classification accuracy on real-test is 82%, and the LSTM’s (2.0s window) accuracy is 81%; both modest improvements over the 73% reported by the RoCoG paper’s authors.
- Models trained on real-train (n=204) outscored models trained on sim-train (n=1980) when evaluated on real-test (n=100).
- The average values hide the per-class discrepancies: adding real training data improves per-class performance, not new model architectures.
- Temporal evaluation in the last table is particularly eye-opening: 204 real training clips (0.2517) essentially tie 1,980 synthetic + 204 real (0.2542), and both beat synthetic alone (0.1497). At this scale the real clips drive the performance.
If there’s a common theme here, it’s that model performance varies widely based on the inputs and the largest variance in model performance comes from the data itself. FiftyOne allowed me to systematically find which variables were important for model performance.
Finally, the moment of truth. How does the model, trained on open-source data, perform on my robot when I give it gestures in the wild?
Step 6: Zero-shot evaluation on in-the-wild robot data
I recorded my own version of the gesture dataset in the wild. In total, my in-the-wild dataset had all 7 gestures, recorded across 4 different scenes, 3 different roles, recorded with/without verbal commands, and 5 repetitions each. In total, I have 7*4*3*2*5 = 840 clips that the model has not seen at all.
Each clip had ground truth labels but no temporal window. I applied the “wrist over elbow” rule from earlier to generate the temporal labels, and validated them against a few manually-annotated samples to ensure there was good IoU overlap. The “wrist over elbow” rule matched my manual annotations at .81 median IoU, so I then applied the rule to the remainder of the 840 samples of the in-the-wild dataset.
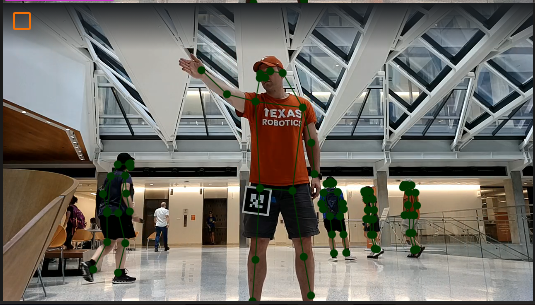
One quick note: RoCoG data is sampled at ~30 frames per second, while my robot camera captured images at ~17 FPS.
Finally, I applied the trained causal models to the in-the-wild dataset and ran an ActivityNet-style eval*.
*One quick note about ActivityNet evaluation: the mAP isn’t computed over all 840 samples, only the ones with valid scorable temporal window (n=719)
Here’s how the final models performed on my in-the-wild dataset:
| Model | Training set | Clip accuracy | Temporal mAP |
|---|---|---|---|
| LSTM, 2s window | synthetic | .448 | .207 |
| LSTM, 2s window | synthetic+real | .513 | .229 |
| TCN, 2s window | synthetic+real | .471 | .222 |
And here’s the per-gesture breakdown for the LSTM, 2s model trained on synthetic+real:
| Gesture | Clip accuracy | Temporal mAP |
|---|---|---|
| Advance | .383 | [not run] |
| Attention | .192 | .026 |
| FollowMe | 1.00 | .784 |
| Halt | .025 | .000 |
| MoveForward | 1.00 | .621 |
| Move | .000 | .000 |
| Rally | .992 | .510 |
Key takeaways:
- Headline accuracy improved from 24% in my 2024 paper to 51.3% in this iteration, a > 2X improvement. Notable because the 2024 version included the in-the-wild data in training, and this time it trained only on RoCoG.
- Once again, the per-class table and eval runs reveal nuance around the overall metrics:
- Advance has no valid temporal predictions in this split - hence the mAP value could not be computed.
- FollowMe, MoveForward and Rally are near-perfectly accurate and have temporal mAP > 0.5
- Attention, Halt, and MoveInReverse are effectively impossible to classify or localize temporally - at or below chance level.
The model is highly dependent on the specific class/gesture, and temporal detection and classification are two separate metrics entirely.
Still, this is a massive headline improvement over what I did before, and the additional information from each phase provided more insight than I could have ever gleaned from my Jupyter notebook in 2024.
What actually closed the sim-to-real gap
I’ve talked a lot about different phases of model training, and have gone on some interesting tangents. But to summarize, here’s what actually moved the needle on model performance:
| Change | Metric | Before | After | Delta |
|---|---|---|---|---|
| Normalize pose keypoints to skeleton, not image frame | sim-val clip accuracy | .44 | .61 | + .17 |
| Whole-clip LSTM → causal 2s sliding window model (synthetic training data only) | real-test clip accuracy | .47 | .64 | + .17 |
| Add 204 real clips to 1,980 synthetic training clips | real-test clip accuracy | .64 | .81 | + .17 |
| Extend causal model window from 0.5s to 2.0s (LSTM and TCN) | sim-val window accuracy | .861 | .930 | + .069 |
| Unify labeling convention across domains | sim-val temporal mAP | .470 | .287 | - .183 |
| Zero-shot performance on in-the-wild dataset (840 never-before-seen clips) | clip classification accuracy | .240 | .513 | + .273 |
So in total, we’ve quantified the effects of feature normalization, model architecture, and sim/real training data on model performance. We also see that unifying the labeling convention results in an apparent degradation; note that this isn’t a change in model performance, but a change in its evaluation criteria that was overlooked before I had a chance to investigate with FiftyOne.
These allowed me to make a substantial performance improvement over my 2024 model.
References
If you’re interested in the RoCoG dataset, see the paper:
A. V. Reddy et al., “Synthetic-to-Real Domain Adaptation for Action Recognition: A Dataset and Baseline Performances,” in IEEE International Conference on Robotics and Automation (ICRA), 2023.
The RoCoG GitHub repo can be found here: https://github.com/reddyav1/RoCoG-v2
Both are used under CC by 4.0.
Here is the paper for my original gesture classifier:
Duncan, John A. et al., “C2HI: Towards a Command and Control Hierarchical Interface for Human-Robot Teams in Dynamic Social Environments,” in 2025 IEEE Engineering Reliable Autonomous Systems (ERAS), 2025.
Appendix: YOLO-pose prelabeling code snippets
import cv2
import fiftyone as fo
import fiftyone.core.storage as fos
from ultralytics import YOLO

model = YOLO("yolo11n-pose.pt")

for sample in dataset.iter_samples(autosave=True, progress=True):
    # Pull locally if media stored in the cloud
    with fos.LocalFile(sample.filepath, mode="r") as local_path:
        cap = cv2.VideoCapture(local_path)
        frame_number = 0
        while True:
            ok, frame = cap.read()
            if not ok:
                break
            frame_number += 1
            h, w = frame.shape[:2]

            result = model(frame, verbose=False)[0]
            if result.keykeypoints.xy) == 0:
                continue

            # Most-confident person: RoCoG clips have exactly one subject.
            i = int(resul
            if float(result.boxes.conf[i]) < 0.25:
                continue

            sample.frames fo.Keypoints(
                keypoints=[fo.Keypoint(
                    label="person",
                    # Fifed to [0, 1]
                    points=[(x / w, y / h)
                            for x, y in result.keypoints.xy[i].tolist()],
                    confidence=result.keypoints.conf[i].tolist(),
                )]
            )
        cap.release()
To turn the 17 points into a skeleton, use this snippet:
dataset.skeletons = {"keypoints": fo.KeypointSkeleton(
    labels=COCO17_LABELS, edges=COCO17_EDGES,
)}
dataset.save()
Questions? We have answers.
It is the drop in accuracy when a gesture classifier trained on synthetic clips is run on real footage, and in this project it turned out to be five separate problems rather than one. The five were feature-space separation between synthetic and real embeddings, apparent person scale varying by up to 2.8×, a labeling convention mismatch worth about 40% of the apparent gap, forearm foreshortening from the aerial camera perspective, and a residual 14-point accuracy gap that only real training data closed.
Partly. Trained only on RoCoG-v2 synthetic clips, the LSTM scored 47% accuracy on real test clips it had never seen, well above the 14.3% chance floor but about 14 points below its synthetic performance. Adding 204 real clips to 1,980 synthetic ones pushed real-test accuracy to 81%.
In this project, 204 real clips beat 1,980 synthetic clips on real test data, .760 accuracy against .590. The transfer is asymmetric: training on real clips transferred to real and not at all to synthetic (.237), while training on synthetic clips transferred partway to both.
The data, by a wide margin. Window length was the most important model parameter, worth about +.069 accuracy from 0.5 to 2.0 seconds, while the choice between LSTM and a temporal convolutional network was worth about .005, less than the .017 variance from a different random seed.
This project used a rule-based scheme in place of manual annotation: the gesture begins the first time the wrist keypoint rises above the elbow keypoint and ends the last time it drops below. Against hand-annotated samples the rule hit .970 median IoU on RoCoG-v2 clips and .81 on in-the-wild robot footage, and the resulting windows were stored as
fiftyone.TemporalDetection labels.Machine Learning Engineer
I'm a customer success machine learning engineer here at Voxel51, where I work with our enterprise customers to implement their ML workflows in FiftyOne. I earned my Ph.D. in Robotics from UT-Austin, where I specialized in multimodal perception for command and control of robots in dynamic, unstructured environments.
See all articles by John Duncan
Try Voxel51 for yourself
Related posts
Boost your visual and physical AI workflows.