Few-Shot Image Classification: Prompted VLMs vs. Specialist Models
Oct 23, 2026
• 13 min read
In this article
Key takeawaysWhy foundation models still need domain knowledgeA new way to teach models with in-context learningWhen examples can close the domain knowledge gapWhen more context can't fix a capability gapWhen to stop prompting VLMs and start training specialist modelsPrompting VLMs with Agentic LabelingPhysical AI has a domain knowledge problemFAQ
Try Voxel51 for yourself
The future of data labeling isn't choosing between foundation models and specialist models. It's finding the fastest way to transfer domain expertise into the right model at the right time.
Ask a frontier vision language model (VLM) to classify photos of rock samples into 35 geological categories, and it performs poorly. But give it just two labeled examples of each category, and its macro-F1 jumps from 20% to 73%. No training, no fine-tuning. Just a few examples to show the model which distinctions matter.
For physical AI, this opens up an interesting possibility. What if you could use the visual knowledge already in foundation models to bootstrap labeling for your own domain? Instead of manually annotating hundreds or thousands of images before training a specialist model, you could show an VLM a few examples, review its predictions, and use those corrections to build a labeled dataset.
Using prompted VLMs through tools like Agentic Labeling, teams can generate initial annotations from a handful of examples, review and correct predictions, and gradually build the labeled dataset needed to train a specialist model. The goal is to get useful labels with less human effort upfront.
But there's a catch. This approach only works if the foundation model already has enough visual understanding to recognize the distinctions that matter. And sometimes, it doesn't.
I've spent much of this year testing VLMs across 11 specialized visual datasets to understand how much domain knowledge they need to perform well. I compared class names, written descriptions, and labeled examples, along with specialist models trained on the same tasks.
A pattern emerged: many tasks that appear hard for foundation models aren't inherently difficult. They're just niche. A handful of examples can close much of the knowledge gap. Other tasks barely improve with additional context, no matter how many examples you provide.
Join us on November 9 for a deep dive into the findings and practical tips for prompting VLMs to label specialized datasets. Compute will be provided by Nebius AI Cloud.
Key takeaways
- A few labeled examples can make a dramatic difference. Adding one labeled example per class improved VLM macro-F1 on 10 of the 11 datasets I tested.
- Some tasks are niche, not inherently hard. On drill-core rock classification, macro-F1 jumped from 20% to 73% with just two labeled examples per class.
- Prompting and training have different advantages. Specialist models, including a fine-tuned ConvNeXt-T and a DINOv2 linear probe, sometimes overtook prompted VLMs with as few as 5–10 labeled images per class.
- More context can't always fix a capability gap. On the DermaCon dermatology dataset, additional examples barely improved performance. Some diagnostic distinctions may require clinical information that isn't available in the images.
- VLMs can help bootstrap specialist models. Use in-context learning to generate initial labels, validate them with expert feedback, and train a specialist when the growing dataset and production requirements justify it.
Why foundation models still need domain knowledge
In the late 1970s, researchers at SRI International set out to build a computer that could find mineral deposits. The program couldn't identify rocks on its own, so they brought in geologists and interviewed each of them for about 50 hours. Programmers then translated their chains of reasoning into rules the computer could follow.
They called the expert system PROSPECTOR. In 1982, it successfully identified a promising molybdenum deposit in Washington state, and the discovery made the pages of Science.
But PROSPECTOR had a limitation: it could only recognize the distinctions its experts had explicitly taught it. Nearly 50 years later, transferring specialized knowledge into AI systems remains a challenge. Consider DCID-35, a dataset of nearly 35,000 drill-core images spanning 35 rock types. Many look nearly identical to an untrained eye, but geologists know which distinctions matter.
Nearly 50 years later, frontier models are dramatically more capable, but the knowledge acquisition bottleneck hasn't disappeared. A factory inspector can distinguish a copper burr from a scratch on a circuit board. An agronomist can identify dozens of crops from drone imagery. These are distinctions learned through years of experience in a specialized domain, and they aren't necessarily distinctions a foundation model has learned to make.
Frontier models, by contrast, learn concepts from the data available during pretraining, much of it drawn from the public internet. But the concepts industry needs are often defined by processes, environments, and criteria that the public internet never captures. The evidence is unforgiving: zero-shot accuracy on a visual concept follows a log-linear relationship with its frequency in the pretraining corpus (Udandarao et al., 2024).
No frontier model can be pretrained on every specialized concept that matters to every industry. But that doesn't necessarily mean these concepts are beyond the model's capabilities. A model might already have the visual understanding needed to recognize a particular defect, without knowing how an expert defines it. The challenge is finding a way to transfer that knowledge to the model without having to train it from scratch.
A new way to teach models with in-context learning
I've spent the last few years taking whacks at operationalizing a version of this problem: how can we transfer knowledge from a domain expert into a learning system with as little friction as possible? Increasingly, I think the answer lies in in-context learning (ICL): the ability of a model to learn a new task from examples provided at inference time, without retraining or updating its parameters.
I didn't arrive at ICL immediately. I experimented with interactive model training, where experts could provide feedback as a model learned, and more experimental approaches like "neural Lego bricks," which let experts build specialized concepts from simpler ones a foundation model already understood.
Some worked surprisingly well, but they were difficult to put into practice. They required substantial engineering work to build and maintain, slowed down iteration, and often proved brittle. I wanted a way for experts to teach models what they knew without needing an ML engineer to build and maintain a custom system around them.
This is what makes the recent progress in visual in-context learning so interesting to me. Unlike conventional model training, ICL doesn't require updating model weights. Instead, a pretrained model receives a set of demonstrations, typically input–output pairs, alongside a new query. It uses those examples to infer the task and produce an answer, adapting its behavior through the forward pass alone.
I believe we're approaching the point where visual ICL is capable enough to become the engine I've been looking for: a way for experts to teach models new concepts simply by showing them what they mean.
To understand how far this approach could go, I tested VLMs across 11 specialized visual datasets, comparing performance with different numbers of labeled examples and against trained specialist models. Three datasets illustrate the different outcomes:
- Drill-core rock classification: A domain knowledge gap. The VLM started at 20% macro-F1 with class names alone but reached 73% with just two labeled examples per class. A specialist model overtook it with around four labeled images per class and approached 100% with more training data.
- Ceramic-substrate defects: Prompting and training work at different scales. The VLM improved from 34% macro-F1 to 59% with one labeled example per class, reaching 78% with 20. It performed well with limited labeled data, but a trained specialist eventually pulled ahead.
- Dermatology: More examples aren't always enough. Neither the VLM nor the trained specialist performed particularly well, and additional examples produced little improvement. Some diagnoses require clinical information that isn't available in photographs alone, which may help explain why prompting didn't improve performance.
When examples can close the domain knowledge gap
One dataset I experimented with illustrates this particularly well: Ceramic-defect, a collection of 7,689 images of surface defects on ceramic substrates used in semiconductor packaging. The images fall into six categories: abnormal thickness, adhesion, edge defect, scar, spot, and uneven.
I wanted to see whether a pretrained VLM could learn to distinguish these defects from a handful of examples, without any fine-tuning. I started by asking the model to classify images using only the six category names. Then I added labeled reference images directly to its prompt, giving it examples of what each defect looked like.
The difference was immediate. In one test, the model classified an adhesion defect as a scar when given only the category names. With one labeled reference image per class, it correctly identified the same image as adhesion. The model hadn't been retrained. It simply had more context for interpreting the categories.
This wasn't an isolated result. With class names alone, the VLM achieved about 34% macro-F1 on the held-out test set. Adding just one labeled example per class increased that score to 59%. With 20 examples per class, it reached 78%.
I also compared this approach with two trained specialists: a fine-tuned ConvNeXt-T and a DINOv2 linear probe. With very little labeled data, the prompted VLM performed better. As more training data became available, the specialists caught up and eventually surpassed it, with the best reaching 93% macro-F1 using the full training set.
Because these examples are provided at inference time, developers can test the approach without collecting a large training dataset or fine-tuning a model.
But was this specific to ceramic defects?
I repeated the one-example experiment across 11 datasets, comparing performance with class names alone against performance with one labeled reference image per class. The additional examples improved macro-F1 on 10 of the 11 datasets. For drill-core rock classification, the gain was particularly large, approaching 40 percentage points.
The results suggest that many seemingly difficult classification tasks are really problems of unfamiliar domain knowledge. The model may already have the visual capabilities needed to distinguish the categories, but not know which distinctions are relevant. A few examples can help bridge that gap.
This is consistent with previous research on in-context learning.
- Examples can tell a model which task it's doing. Pan et al. showed that a few examples are often enough for a model to recognize a task and apply what it already knows.
- Prompts can activate knowledge a model already has. Xie et al. proposed that in-context learning helps models identify concepts learned during pretraining.
- Task-specific solutions may already be close to pretrained models. Gan and Isola showed that specialized solutions are so ubiquitous around pretrained weights that even random perturbations can recover them.
With the above works in mind, it's not difficult to imagine how even a few examples can drastically improve VLM performance on specialized tasks.
There was, however, one holdout—DermaCon, a specialized, open-access dermatology image dataset.
When more context can't fix a capability gap
DermaCon is a very different kind of dataset: a few thousand clinical photographs of skin conditions spanning 19 diagnoses, some with barely a dozen examples.
The results were disappointing across the board. A specialist classifier trained on every available labeled image achieved a macro-F1 score of just 25.1%, while a VLM prompted with class names alone scored 20%. With 19 classes, random guessing would yield approximately 5%.
What surprised me was how little additional context helped. On the previous datasets, giving a model a few labeled examples was often enough to clarify an unfamiliar category and substantially improve its predictions. Here, adding examples barely moved the needle. At two examples per class, the VLM reached just 0.235 macro-F1. The same pattern held across every VLM I tried (including Gemma 4 31B, the GPT 5.6 line, the GPT 6 line, GPT 6.1 Sol, GLM 5.3, Claude Opus 5, ).
Neither approach performed particularly well. And that points to a different kind of problem than the ones we encountered with the ceramic-defect and drill-core datasets.
Dermatology is harder because some diagnoses are difficult to distinguish from photographs alone, even for a trained expert. A dermatologist may also consider patient history, symptoms, and how a lesion has changed over time. That information wasn't available to the models. Showing them more examples of visually similar conditions couldn't necessarily supply the evidence needed to tell those conditions apart.
The ceramic-defect task is niche. The dermatology task is hard.
Context can close the gap in the first case. The second may require better reasoning, finer-grained perception, more training data, or information that isn't available in the image at all. If the model doesn't have the capabilities needed for the task, you can keep refining the prompt all day without solving the underlying problem.
When to stop prompting VLMs and start training specialist models
The question isn't just whether a VLM can learn a specialized task from a few examples. It's also how its performance compares with a trained specialist as more labeled data becomes available.
Three datasets illustrate that tradeoff.
In the comparisons I ran, prompted VLMs generally performed better when there were only a handful of labeled examples per class. As I added more training data, the specialist models began to pull ahead, in some cases with as few as 5–10 examples per class. That's not a universal threshold (and it’s one that’s rapidly moving in favor of VLMs), but it illustrates why prompting and training can be useful at different stages of a labeling workflow.
At first glance, that might seem like an argument for training a specialist almost immediately. If it only takes a handful of labeled examples to outperform a foundation model, why wouldn't you?
Because the point where a specialist becomes more accurate isn't necessarily the point where it becomes worth training one. Even with pretrained backbones, training introduces engineering overhead: building pipelines, validating performance, and maintaining the model as data distributions or labeling criteria change. Prompted VLMs let you experiment with new concepts simply by changing the instructions and examples, without retraining.
And prompting and training aren't mutually exclusive. An VLM can help generate the first labels, which experts can review and correct before using them to train a specialist. As the task matures, a trained model may offer better accuracy, latency, or inference costs.
That's the opportunity I find most exciting: lowering the cost of getting started means we can tackle specialized problems that might never have justified a large annotation effort in the first place.
| Type of task | Performance considerations | Operational considerations | Recommended approach |
|---|---|---|---|
| Familiar concepts | Pretrained models can often recognize categories without labeled examples. | Minimal setup, no task-specific training, and easy to adapt as requirements change. | Start with zero-shot VLM. Add examples if needed. |
| Specialized, learnable categories | Few-shot VLMs perform well with limited labels. Specialists can surpass them as labeled data accumulates. | Prompting is fast to bootstrap and flexible as categories evolve. Training adds pipeline development, evaluation, and maintenance overhead, with greater risk of instability when labels are scarce. | Prompt first, train when justified. Use VLMs to bootstrap labels; invest in specialists when accuracy, inference cost, latency, or scale warrants it. |
| Genuinely difficult tasks | Neither prompting nor small scale specialist training necessarily overcomes missing information or model capability limitations. | Collecting more labels and retraining can become expensive without addressing the underlying problem. | Rethink the approach. Add missing context, use specialized tools, or change models before investing in more training. |
Prompting VLMs with Agentic Labeling
The experiments show that a handful of examples can make foundation models surprisingly effective on specialized labeling tasks. But putting that into practice takes more than writing a good prompt.
Without a dedicated workflow, an ML engineer has to write code to assemble prompts, select and label reference images, call a model API, and map predictions back to the dataset. Every change to the examples, instructions, or label taxonomy requires another round of updates and testing. Reviewing predictions and correcting mistakes adds yet another layer of work.
We built Agentic Labeling in Voxel51 to make that process more accessible. Rather than requiring engineers to build and maintain custom prompting pipelines, we want to make it easier to teach models through examples and feedback.
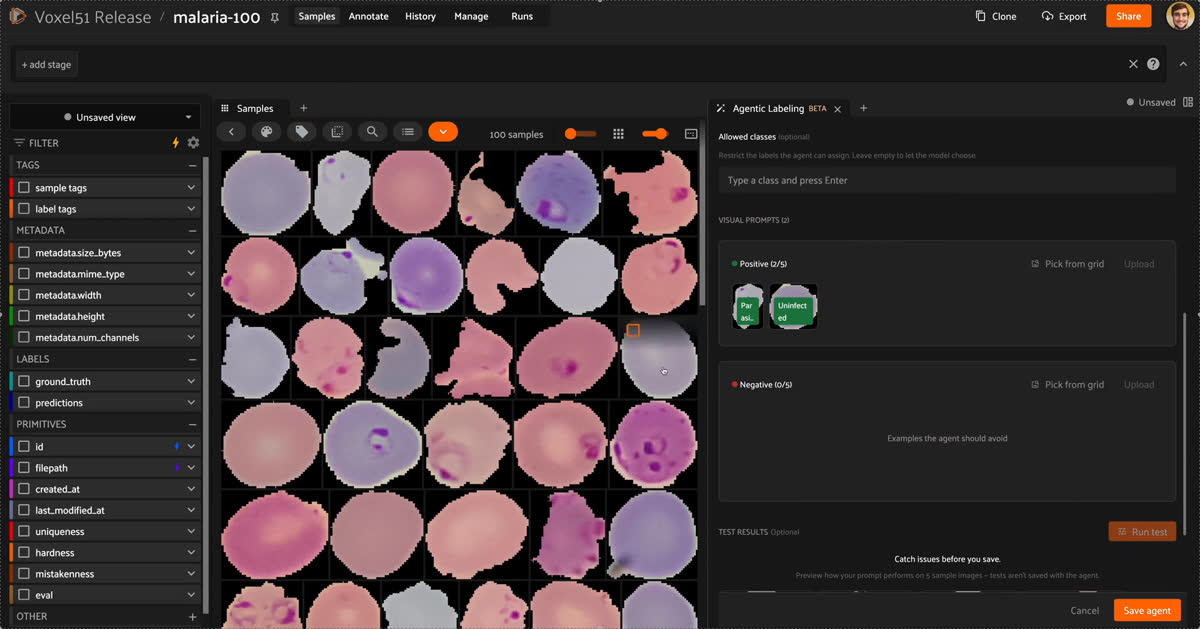
- Define the task. Describe what you want to label, specify the categories and constraints, and provide representative examples.
- Preview and refine. Generate predictions on a small batch, review the results, and adjust the instructions or examples until the model reliably applies your labeling criteria.
- Scale what works. Apply the refined labeling workflow across your dataset instead of manually annotating every sample.
- Train a specialist when it makes sense. Use the growing collection of validated labels to train a task-specific model as the dataset grows.
The underlying idea is simple: if prompting is often enough to bootstrap a specialized labeling task, using it should be as easy as navigating a UI.
Join the workshop on November 9 for a deep dive into the findings and practical tips for prompting VLMs to label specialized datasets. Compute will be provided by Nebius AI Cloud.
Physical AI has a domain knowledge problem
Nearly 50 years after PROSPECTOR, the knowledge acquisition bottleneck is still with us. This insight is neither unique nor new: Palantir built much of its business around forward-deployed engineers (FDEs) who work directly with customers to translate their expertise and workflows into software. More recently, frontier AI labs like OpenAI and Anthropic have invested in similar roles. Even as models become more capable, making them useful in specialized environments still requires getting knowledge out of the people who understand those environments.
As one FDE told The New Stack: “The model is usually the cleanest part. The hard part is finding the workflow nobody documented, the data source people actually trust, and the person who knows why the process works that way.”
This is especially true in physical AI. The knowledge needed to recognize a manufacturing defect, identify an unsafe behavior in a warehouse, or classify an unusual driving scenario often comes from people who have spent years working in those environments.
PROSPECTOR needed 50 hours of interviews to capture one geologist's expertise. Today, that same expert could point at a dozen photos, correct 80 predictions over a cup of coffee, and turn a nearly useless model into a passable annotator by lunch.
The broader opportunity is to make transferring domain expertise into AI systems faster and less expensive. Figuring out whether a task needs better instructions, more examples, or a trained specialist is a search problem, and it should be the tool's search, not the expert's.
We are always a few shots away. The job is to find out which shots, get them from the people who have them as efficiently as possible, and know when to stop prompting and start training.
FAQ
A prompted VLM is usually the better starting point when you have only a handful of labeled examples per class. In these experiments, trained specialists pulled ahead at about 6 to 14 labeled images per class. Training one still adds pipeline and maintenance costs.
One labeled example per class improved VLM macro-F1 on 10 of 11 specialized visual datasets. On ceramic-substrate defects, one example per class raised macro-F1 from 34% to 59%, and 20 examples per class reached 78%.
VLMs often struggle because the task is niche, not because it’s hard. The model may already have the visual capability but not know which distinctions matter. Zero-shot accuracy also tracks how often a concept appears in pretraining data.
No. On DermaCon, VLM macro-F1 stayed between about 20% and 28% regardless of the number of examples. Some diagnoses need patient history or changes over time that an image doesn’t contain.
Agentic Labeling is a Voxel51 workflow for labeling data with VLMs from instructions and examples. You define the task, preview and refine predictions, scale what works across the dataset, and train a specialist from the validated labels.
Try Voxel51 for yourself
Loading related posts...
© 2026 Voxel51 All Rights Reserved