VLM blog posts
Vision-language models (VLMs) connect what a model sees to what it can say. These posts put VLMs to work in FiftyOne: auto-labeling, visual grounding, dataset querying, and hands-on evaluations of new models as they release.
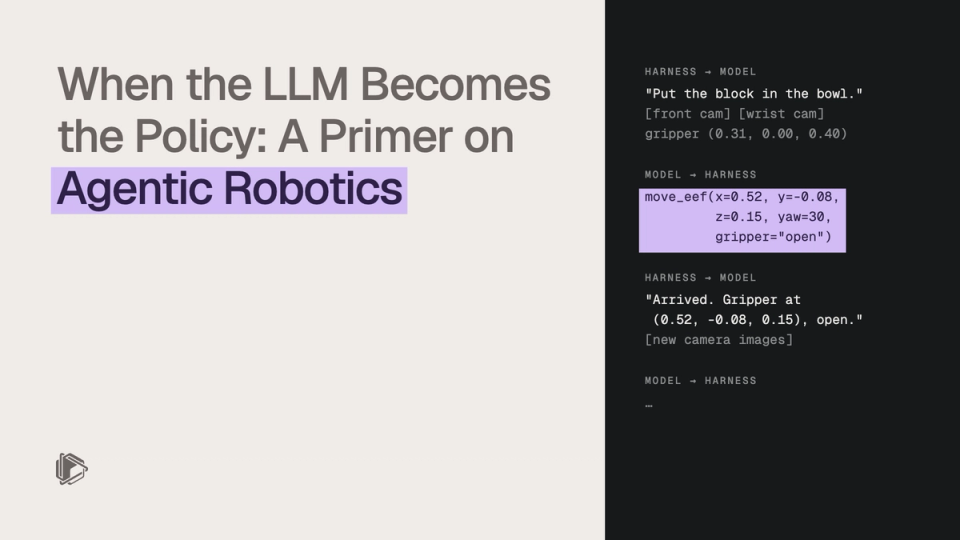
by Mohamad Louai Shehab, Guest author
Physical AI
• 
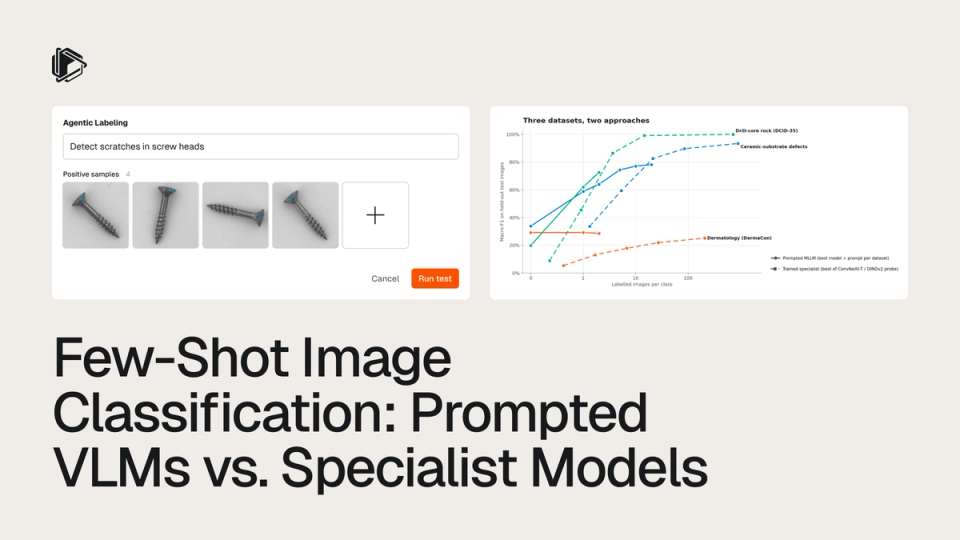
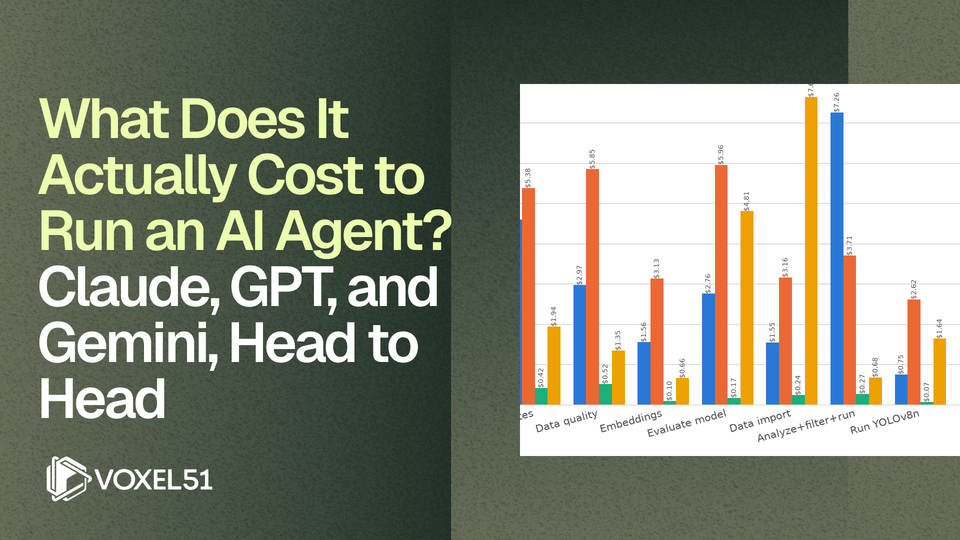
by Jacob Sela, Machine Learning
Data annotation
• 
by Adonai Vera, DevRel
Model evaluation
• 
by Harpreet Sahota, DevRel
Model evaluation
• 
by Adonai Vera, DevRel
Data annotation
• 
by Jimmy Guerrero, Leadership
Search
• 
by Jacob Sela, Machine Learning
Data annotation, Product and news
• 
Enough data wrangling.
Request a demo.