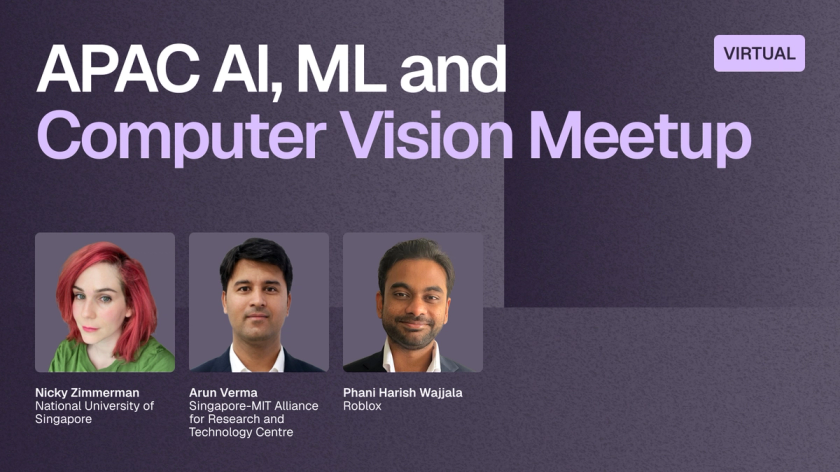
Register for the Zoom
Build better computer vision models.
- Annotate samples
- Curate datasets
- Evaluate models
Oct 01, 2026
6:00 PM - 8:00 PM PDT
Online. Register for the Zoom!
Speakers
About this event
Join our virtual meetup to hear talks from experts on cutting-edge topics across AI, ML, and computer vision.
Schedule
Sign Language: Towards sign understanding for robot autonomy
Navigational signs are common aids for human wayfinding and scene understanding, but are underutilized by robots. We argue that they benefit robot navigation and scene understanding, by directly encoding privileged information on actions, spatial regions, and relations.
Interpreting signs in open-world settings remains a challenge owing to the complexity of scenes and signs, but recent advances in vision-language models (VLMs) make this feasible. To advance progress in this area, we introduce the task of visual sign grounding, which parses locations and associated directions from signs, and maps them to region in the sign’s local environment.
Additionally, we present a baseline approach using VLMs, and demonstrate their promise on the task. We also outline different applications, such as localization and navigation, which benefit from the spatial-symbolic information encoded by navigational signs.
MeMo: Memory as a Model
Large language models (LLMs) achieve strong performance across a wide range of tasks, but remain frozen after pretraining until subsequent updates. Many real-world applications require timely, domain-specific information, motivating the need for efficient mechanisms to incorporate new knowledge.
In this paper, we introduce MeMo (Memory as a Model), a modular framework that encodes new knowledge into a dedicated Memory model while keeping the LLM unchanged. Compared to existing methods, MeMo offers several advantages: (a) it captures complex cross-document relationships, (b) it is robust to retrieval noise, (c) it avoids catastrophic forgetting in the LLM, (d) it does not require access to the LLM’s weights or output logits that enabling plug-and-play integration with both open and proprietary LLMs, and (e) its retrieval cost is independent of corpus size at inference time.
Our experiments on three benchmarks, BrowseComp-Plus, NarrativeQA, and MuSiQue, show that MeMo achieves strong performance compared to existing methods across diverse settings.
Beyond Exact Matches: Detecting Modified 3D Assets at Marketplace Scale
How can a marketplace identify copied 3D assets when their orientation, geometry, or composition has changed? Drawing on my work in 3D content understanding at Roblox, this talk will explore multi-view and rotation-invariant representations for similarity and duplicate detection, including the challenges posed by deformed and fragmented copies.
It will examine how geometric and semantic signals can complement one another, and discuss practical trade-offs in evaluating detection quality and deploying these methods at scale. The presentation will draw on published patent applications and publicly shareable examples to offer practical lessons for engineers building visual search, content-understanding, and marketplace-safety systems.
You might also enjoy these events

Virtual
MCP/Agents/Skills Meetup - October 8, 2026
Join our virtual meetup to hear talks from experts on cutting-edge topics across AI, ML, and computer vision.
Oct 8, 2026

Virtual
AI, ML and Computer Vision Meetup - September 24, 2026
Join our virtual meetup on September 24 to hear talks from experts on cutting-edge topics across AI, ML, and computer vi...
Sep 24, 2026
© 2026 Voxel51 All Rights Reserved