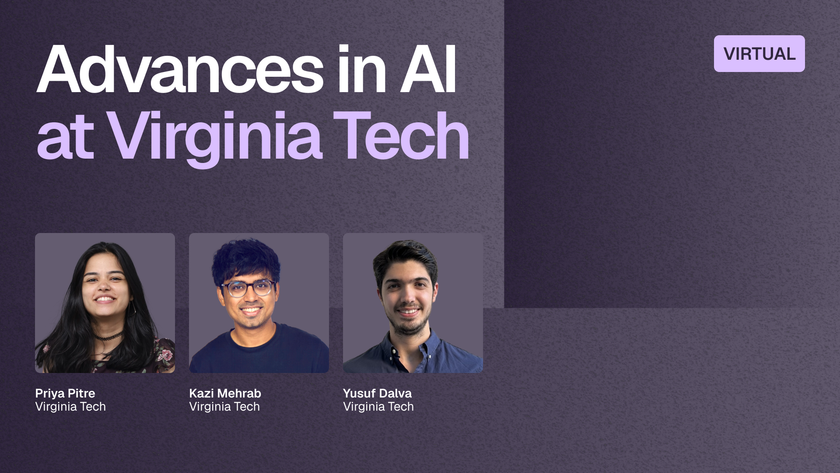
Register for the Zoom
Build better computer vision models.
- Annotate samples
- Curate datasets
- Evaluate models
Oct 22, 2026
9:00 AM - 11:00 AM PST
Online. Register for the Zoom!
Speakers
About this event
Join our virtual meetup to hear talks from experts on cutting-edge topics across AI, ML, and computer vision.
Schedule
Multi-Agent Communication: A framework, diagnostic and mechanistic perspective
Multi-agent LLM systems are increasingly used for collaborative reasoning, debate, and consensus, yet their communication dynamics remain poorly understood. This talk presents a framework for studying multi-agent communication through diagnostic and mechanistic perspectives.
I will discuss CONSENSAGENT, which improves consensus by mitigating sycophancy, alongside our diagnostic work on communication patterns and failure modes in real-world multi-agent debates. I will then present ongoing work that moves toward a mechanistic understanding of how these interaction patterns arise internally, with the broader goal of making multi-agent systems more interpretable, reliable, and controllable.
Exposing and Improving Fine-Grained Visual Grounding Abilities of Lightweight Multimodal LLMs
Lightweight multimodal LLMs can localize whole objects effectively, yet often struggle when a query targets a small object part or fine-grained visual detail. This talk presents a reasoning-guided framework that teaches compact models to ground parts through an explicit coarse-to-fine process: first locating the parent object, then identifying the requested part.
A part-aware reinforcement-learning objective provides stage-wise rewards for object accuracy, part containment, and the consistency of the model’s self-critique. Using these techniques, a compact 4B-parameter model achieves state-of-the-art zero-shot part grounding while preserving its object-level performance.
These advances can be used to enable lightweight MLLMs to support detail-oriented tasks in biology and robotics.
Understanding Visual Generative Models for Precise Control
Despite remarkable progress in image and video generation, translating user intent into precise and consistent visual outputs remains a challenge. This talk explores how understanding the representations within generative models can enable finer control over what they create.
It connects semantic image editing with compositional generation, examining how visual concepts can be isolated, manipulated, and combined while preserving their identity and surrounding content. Building on these insights, structured visual inputs provide a way to express complex intent through subject references, poses, and spatial layouts.
The discussion then extends from images to video, where representations must evolve to preserve scene continuity while accommodating motion and change. Together, these directions establish a unified perspective on how visual representations can support controllable editing, composition, and coherent generation across space and time.
You might also enjoy these events

Virtual
AI, ML, and Computer Vision Meetup - October 15, 2026
Join our virtual meetup to hear talks from experts on cutting-edge topics across AI, ML, and computer vision.
Oct 15, 2026

Virtual
Advances in AI at SDSU - October 14, 2026
Join our virtual meetup to hear talks from experts on cutting-edge topics across AI, ML, and computer vision.
Oct 14, 2026
© 2026 Voxel51 All Rights Reserved