Action chunking is a control technique where a policy predicts a short sequence of future actions at once, rather than deciding one step at a time. Committing to a chunk of actions tends to make motion smoother and reduces the compounding error that accumulates when each step is predicted in isolation. It is a common design choice in modern robot learning, including many vision-language-action models.
Action chunking is the practice of having a control policy output several upcoming actions in one go, instead of predicting just the single next action and then repeating. Rather than deciding move by move, the policy commits to a short plan, a chunk covering the next stretch of time, and executes it before predicting the next chunk. The size of a chunk can range from a handful of steps to many, and the robot follows the predicted sequence rather than replanning at every single moment.
The motivation is to address a well-known weakness of step-by-step control learned from demonstrations. When a policy predicts one action at a time, small errors nudge the robot into situations slightly unlike anything it saw in training, where its next prediction is a little worse, and these mistakes compound until the robot drifts off course. By predicting a coherent chunk of actions at once, the policy produces smoother motion and shortens the effective decision horizon, which reduces how quickly errors can accumulate. This is why action chunking has become a common ingredient in modern robot learning, appearing in influential manipulation methods and in many vision-language-action models.
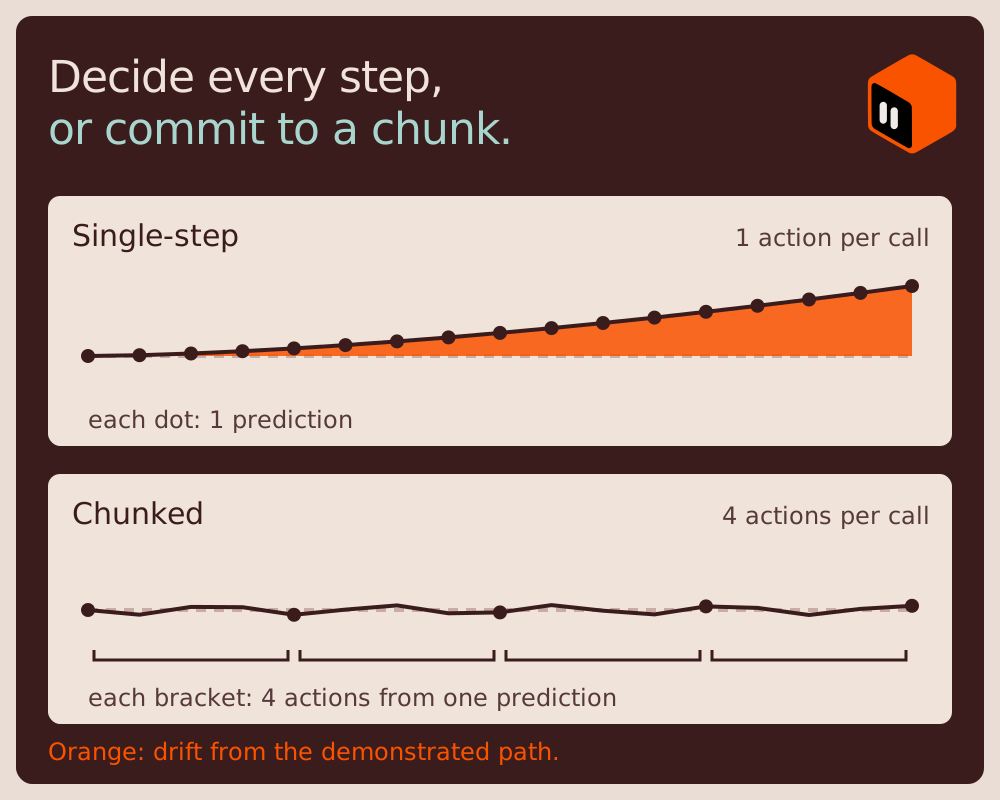
A single-step policy decides at every step. A chunked policy commits to several steps at once, which shortens the decision horizon.
Key takeaways
Action chunking predicts a short sequence of future actions at once, rather than one step at a time.
It tends to make motion smoother and reduces the compounding error of single-step prediction.
It is a common design choice in modern robot learning, including many vision-language-action models.
How it works
A policy that uses action chunking takes the current observation and outputs a block of consecutive actions covering the next several time steps. The robot then executes that block, either running through the whole chunk before predicting again or blending overlapping chunks for extra smoothness. Because the policy commits to a short plan, it does not have to correct itself at every instant, which both smooths the resulting motion and limits how often a fresh prediction can go astray. The trade-off is responsiveness, since committing to a longer chunk means reacting less frequently to new information, so the chunk length is a balance between smoothness and the ability to adapt quickly.
Before you train a chunking policy, find the pauses in your demonstrations
A policy that predicts chunks of actions reproduces the timing of its demonstrations along with the motion. A pause that lasts half a second in one demonstration becomes a chunk of standing still that the policy can learn to emit. The quiet problems:
a regrasp that becomes a chunk of close, open, and close again
datasets recorded at different frame rates, so one chunk length covers different amounts of time
chunk lengths chosen without checking the dataset's frame rate
In Voxel51, LeRobot Community gathers 2,378 tabletop manipulation episodes from 117 community LeRobot datasets, recorded by different people on different setups, so you can see where the arm stands still and for how long.
LeRobot Community
2,378 episodes
Tabletop manipulation episodes from 117 community LeRobot datasets on the Hugging Face Hub, with embeddings, task text, grasp counts, and phase summaries.
Try this: Step through one episode and time the longest stretch where the arm holds still. Count how many actions that pause would fill.
Action chunking matters because it directly attacks compounding error, one of the central reasons imitation-trained robots drift and fail on longer tasks. For anyone studying robot control, it is a clear example of how a simple change in what the policy predicts can substantially improve real-world reliability and smoothness. Its widespread adoption in recent manipulation systems and action models makes it a concept worth understanding for anyone following how modern robots are trained to move.
What is compounding error and how does chunking help?
Compounding error is the way small mistakes in step-by-step prediction push a robot into unfamiliar states, where its next predictions are worse, so errors snowball. By committing to a chunk of actions at once, the policy shortens the effective decision horizon and reduces how often and how quickly these errors can accumulate.
Does a longer chunk always help?
No. Longer chunks give smoother motion and less frequent replanning, but they also make the robot slower to react to new information. The best chunk length balances smoothness against responsiveness, and it depends on the task.
Where is action chunking used?
It appears in influential imitation-learning methods for manipulation and in many vision-language-action models. It has become a common design choice wherever smooth, reliable motion learned from demonstrations is important.
Jesse Mostipak is the Director of Growth at Voxel51, where the work is helping humans find and trust what the brand knows, and teaching the Google knowledge graph and the LLMs answering on their behalf to do the same. That question, how knowledge gets built inside a system, is one Jesse has been chasing for years. Earlier versions of it ran through a New York City high school science classroom, data science and machine learning, and developer relations at Kaggle, Posit (formerly RStudio), and Baseten. The answer doesn't change much depending on whether the learner is a teenager, a software engineer, or a knowledge graph. Jesse holds a Master's in Education from CUNY Hunter College. LinkedIn