In this article
Try Voxel51 for yourself
Using Slicing Aided Hyper Inference
Object detection is one of the fundamental tasks in computer vision. At a high level, it involves predicting the locations and classes of objects in an image. State-of-the-art (SOTA) deep learning models like those in the You-Only-Look-Once (YOLO) family have reached remarkable levels of accuracy. However, one notoriously challenging frontier in object detection is small objects.
In this post, you will learn how to detect small objects in your dataset using Slicing Aided Hyper Inference (SAHI). We’ll cover the following:
Why Is Detecting Small Objects Hard?
They Are Small
First and foremost, detecting small objects is hard because small objects are, well, small. The smaller the object, the less information the detection model has to work with. If a car is far off in the distance, it might only occupy a few pixels in our image. In much the same way humans have trouble making out distant objects, our model has a harder time identifying cars without visually discernible features like wheels and license plates!
Training Data
Models are only as good as the data they are trained on. Most of the standard object detection datasets and benchmarks focus on medium-to-large objects, which means that most off-the-shelf object detection models are not optimized for small object detection.
Fixed Input Sizes
Object detection models typically take inputs of fixed sizes. For instance, YOLOv8 is trained on images with a maximum side length of 640 pixels. This means that when we feed it an image of size 1920x1080, the model will downsample the image to 640x360 before making predictions, decreasing the resolution and discarding important information for small objects.
How SAHI Works
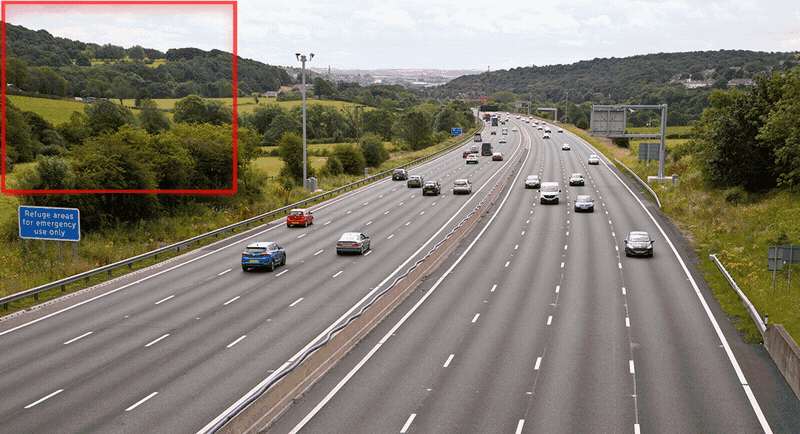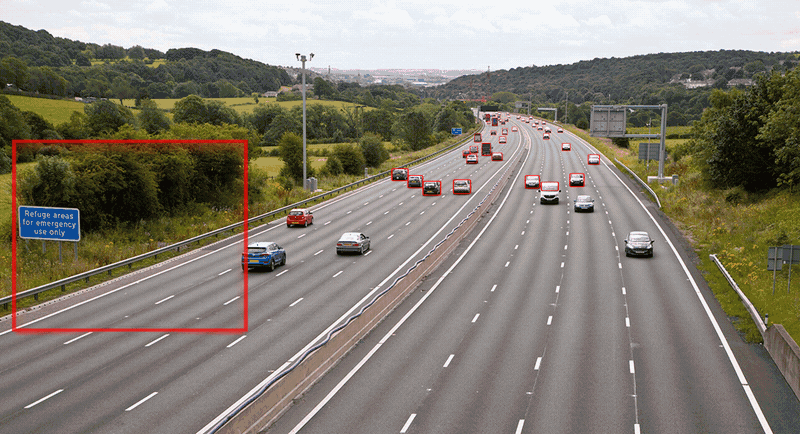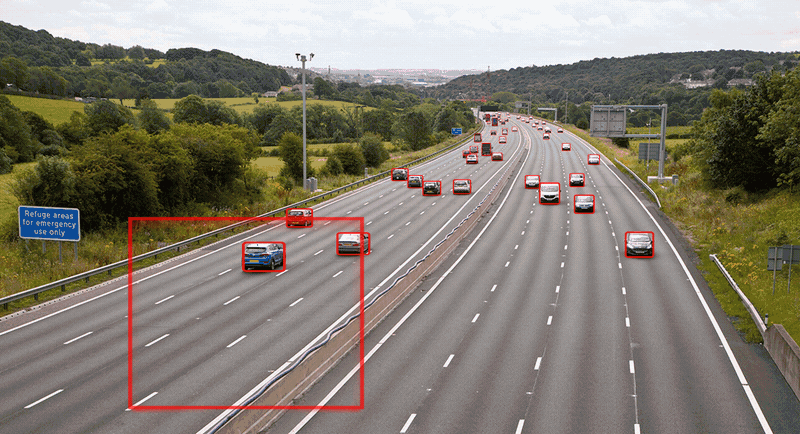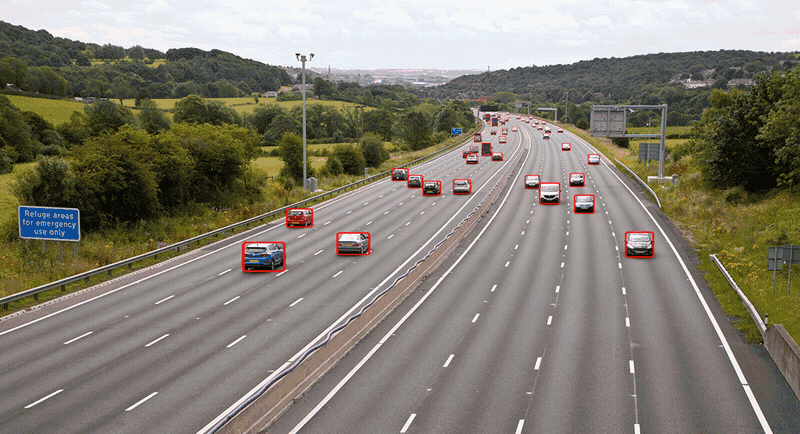
Illustration of Slicing Aided Hyper Inference. Image courtesy of SAHI GitHub Repo.
Theoretically, you could train a model on larger images to improve the detection of small objects. Practically, however, this would require more memory, more computational power, and datasets that are more labor-intensive to create.
An alternative to this is to leverage existing object detection, apply the model to patches or slices of fixed size in our image, and then stitch the results together. This is the idea behind Slicing-Aided Hyper Inference!
SAHI works by dividing an image into slices that completely cover it and running inference on each of these slices with a specified detection model. The predictions across all of these slices are then merged together to generate one list of detections across the entire image. The “hyper” in SAHI comes from the fact that SAHI’s output is not the result of model inference but a result of computations involving multiple model inferences.
💡SAHI slices are allowed to overlap (as illustrated in the GIF above), which can help ensure that enough of an object is in at least one slice to be detected.
The key advantage of using SAHI is that it is model-agnostic. SAHI can leverage today's SOTA object detection models and whatever the SOTA model happens to be tomorrow!
Of course, there is no such thing as a free lunch. In exchange for “hyper inference” you are running multiple times as many forward passes of your detection model, in addition to the processing required to stitch the results together.
Setup
To illustrate how SAHI can be applied to detect small objects, we will use the VisDrone detection dataset from the AISKYEYE team at the Lab of Machine Learning and Data Mining, Tianjin University, China. This dataset consists of 8,629 images with side lengths ranging from 360 pixels to 2,000 pixels, making it an ideal testing ground for SAHI. Ultralytics’ YOLOv8l will serve as our base object detection model.
We will be utilizing the following libraries:
- fiftyone
- huggingface_hub
- ultralytics
- sahi
If you haven't already, install the latest versions of these libraries. You will need
fiftyone>=0.23.8 to load VisDrone from the Hugging Face Hub:pip install -U fiftyone sahi ultralytics huggingface_hub --quietNow in a Python process, let’s import the FiftyOne modules we will use to query and manage our data:
import fiftyone as fo
import fiftyone.zoo as foz
import fiftyone.utils.huggingface as fouh
from fiftyone import ViewField as F
And just like that, we are ready to load our data! We’ll use the
load_from_hub() function from FiftyOne’s Hugging Face utils to load part of the VisDrone dataset directly from the Hugging Face Hub via its repo_id. For demonstration and to keep code execution as fast as possible, we will only take the first 100 images from the dataset. We will also give this new dataset we are creating the name ”sahi-test”:dataset = fouh.load_from_hub(
"Voxel51/VisDrone2019-DET",
name="sahi-test",
max_samples=100
)Before adding any predictions, let’s take a look at our dataset in the FiftyOne App:
session = fo.launch_app(dataset)💡Check out FiftyOne’s Hugging Face Integration for more information.
Standard Inference with YOLOv8
In the next section, we will run hyper-inference on our data using SAHI. Before we bring SAHI into the picture, let’s run standard object detection inference on our data with the large variant of Ultralytics’ YOLOv8 model.
First, we create an
ultralytics.YOLO model instance, downloading the model checkpoint if necessary. Then, we apply this model to our dataset and store the results in the field ”base_model” on our samples:from ultralytics import YOLO
ckpt_path = "yolov8l.pt"
model = YOLO(ckpt_path)
dataset.apply_model(model, label_field="base_model")
session.view = dataset.view()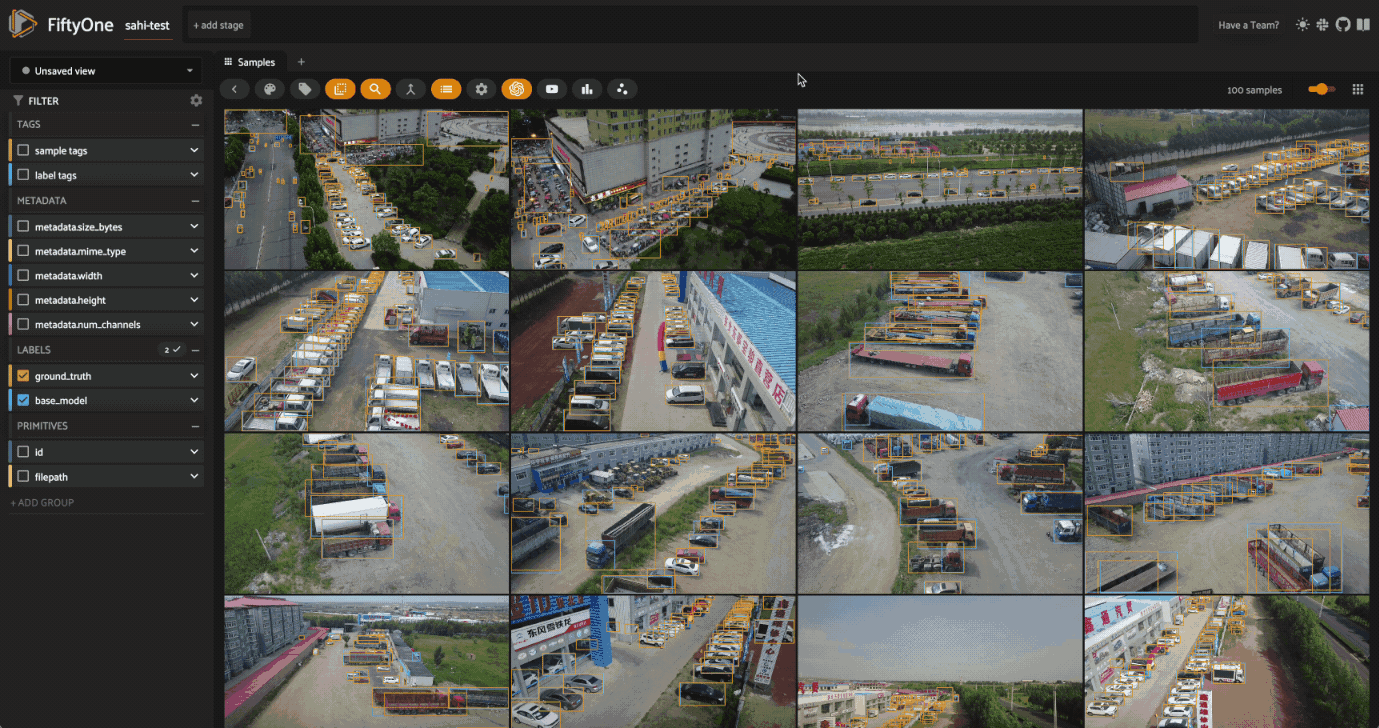
💡Check out FiftyOne’s Ultralytics Integration for more information.
We can see a few things by looking at the model's predictions next to the ground truth labels. First and foremost, the classes detected by our YOLOv8l model are different from the ground truth classes in the VisDrone dataset. Our YOLO model was trained on the COCO dataset, which has 80 classes, while the VisDrone dataset has 12 classes, including an
ignore_regions class.To simplify the comparison, we'll focus on just the few most common classes in the dataset, and will map the VisDrone classes to the COCO classes as follows:
mapping = {"pedestrians": "person", "people": "person", "van": "car"}
mapped_view = dataset.map_labels("ground_truth", mapping)
And then filter our labels only to include the classes we're interested in:
def get_label_fields(sample_collection):
    """Get the (detection) label fields of a Dataset or DatasetView."""
    label_fields = list(
        sample_collection.get_field_schema(embedded_doc_type=fo.Detections).keys()
    )
    return label_fields

def filter_all_labels(sample_collection):
    label_fields = get_label_fields(sample_collection)

    filtered_view = sample_collection

    for lf in label_fields:
        filtered_view = filtered_view.filter_labels(
            lf, F("label").is_in(["person", "car", "truck"]), only_matches=False
        )
    return filtered_view

filtered_view = filter_all_labels(mapped_view)
session.view = filtered_view.view()
Now that we have our base model predictions let’s use SAHI to slice and dice our images 💪.
Using SAHI for Hyper Inference
The SAHI technique is implemented in the
sahi Python package we installed earlier. SAHI is a framework compatible with many object detection models, including YOLOv8. We can choose the detection model we want to use and create an instance of any classes that subclass sahi.models.DetectionModel, including YOLOv8, YOLOv5, and even Hugging Face Transformers models.We will create our model object using SAHI's
AutoDetectionModel class, specifying the model type and the path to the checkpoint file:from sahi import AutoDetectionModel
from sahi.predict import get_prediction, get_sliced_prediction
detection_model = AutoDetectionModel.from_pretrained(
model_type='yolov8',
model_path=ckpt_path,
confidence_threshold=0.25, ## same as the default value for our base model
image_size=640,
device="cpu", # or 'cuda' if you have access to GPU
)Before we generate sliced predictions, let's inspect the model's predictions on a trial image using SAHI's
get_prediction() function:result = get_prediction(dataset.first().filepath, detection_model)
print(result)<sahi.prediction.PredictionResult object at 0x2b0e9c250>Fortunately, SAHI results objects have a
to_fiftyone_detections() method, which converts the results to a list of FiftyOne Detection objects:print(result.to_fiftyone_detections())[<Detection: {
'id': '661858c20ae3edf77139db7a',
'attributes': {},
'tags': [],
'label': 'car',
'bounding_box': [
0.6646394729614258,
0.7850866247106482,
0.06464214324951172,
0.09088355170355902,
],
'mask': None,
'confidence': 0.8933132290840149,
'index': None,
}>, <Detection: {
'id': '661858c20ae3edf77139db7b',
'attributes': {},
'tags': [],
'label': 'car',
'bounding_box': [
0.6196376800537109,
0.7399617513020833,
0.06670347849527995,
0.09494832356770834,
],
'mask': None,
'confidence': 0.8731599450111389,
'index': None,
}>, <Detection: {
....
....
....This makes our lives easy so we can focus on the data, not the nitty-gritty format conversions' details. SAHI's
get_sliced_prediction() function works the same way as get_prediction(), with a few additional hyperparameters that let us configure how the image is sliced. In particular, we can specify the slice height and width, and the overlap between slices. Here's an example:sliced_result = get_sliced_prediction(
dataset.skip(40).first().filepath,
detection_model,
slice_height = 320,
slice_width = 320,
overlap_height_ratio = 0.2,
overlap_width_ratio = 0.2,
)
As a preliminary check, we can compare the number of detections in the sliced predictions to the number of detections in the original predictions:
num_sliced_dets = len(sliced_result.to_fiftyone_detections())
num_orig_dets = len(result.to_fiftyone_detections())

print(f"Detections predicted without slicing: {num_orig_dets}")
print(f"Detections predicted with slicing: {num_sliced_dets}")

Detections predicted without slicing: 17
Detections predicted with slicing: 73
We can see that the number of predictions increased substantially! We have yet to determine if the additional predictions are valid or if we just have more false positives. We'll do this using FiftyOne's Evaluation API shortly. We also want to find a good set of hyperparameters for our slicing. We will need to apply SAHI to the entire dataset to do all of these things. Let's do that now!
To simplify the process, we'll define a function that adds predictions to a sample in a specified label field, and then we will iterate over the dataset, applying the function to each sample. This function will pass the sample's filepath and slicing hyperparameters to
get_sliced_prediction(), and then add the predictions to the sample in the specified label field:def predict_with_slicing(sample, label_field, **kwargs):
result = get_sliced_prediction(
sample.filepath, detection_model, verbose=0, **kwargs
)
sample[label_field] = fo.Detections(detections=result.to_fiftyone_detections())We'll keep the slice overlap fixed at 0.2, and see how the slice height and width affect the quality of the predictions:
kwargs = {"overlap_height_ratio": 0.2, "overlap_width_ratio": 0.2}

for sample in dataset.iter_samples(progress=True, autosave=True):
    predict_with_slicing(sample, label_field="small_slices", slice_height=320, slice_width=320, **kwargs)
    predict_with_slicing(sample, label_field="large_slices", slice_height=480, slice_width=480, **kwargs)
Note how these inference times are much longer than the original inference time. This is because we're running the model on multiple slices per image, which increases the number of forward passes the model has to make. We're making a trade-off to improve the detection of small objects.
Now let's once again filter our labels only to include the classes we're interested in and visualize the results in the FiftyOne App:
filtered_view = filter_all_labels(mapped_view)
session = fo.launch_app(filtered_view, auto=False)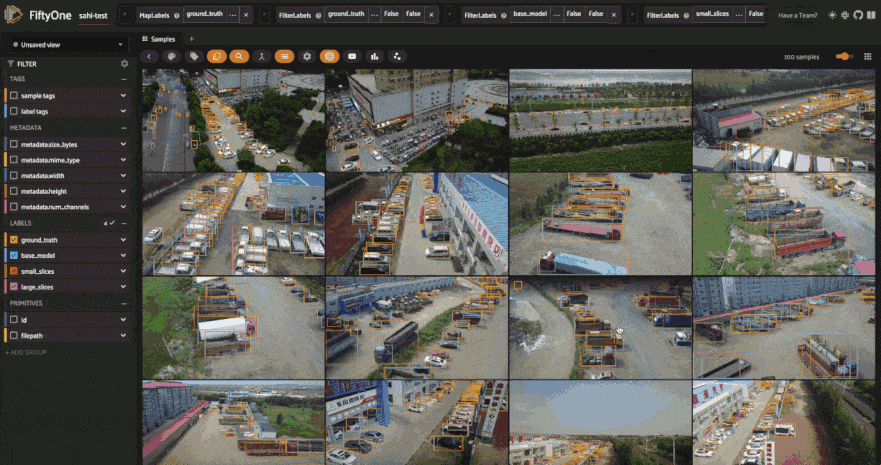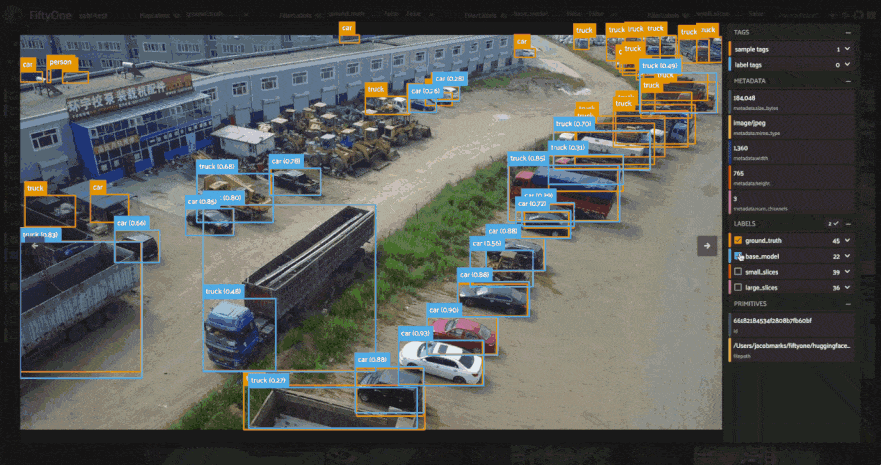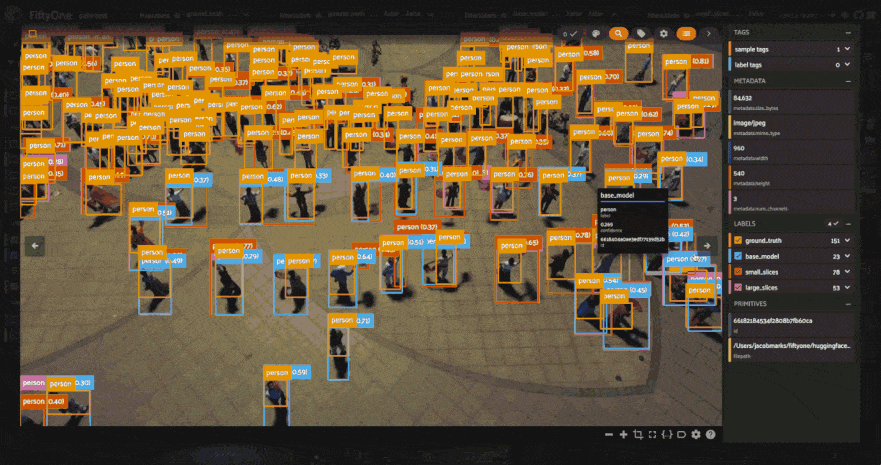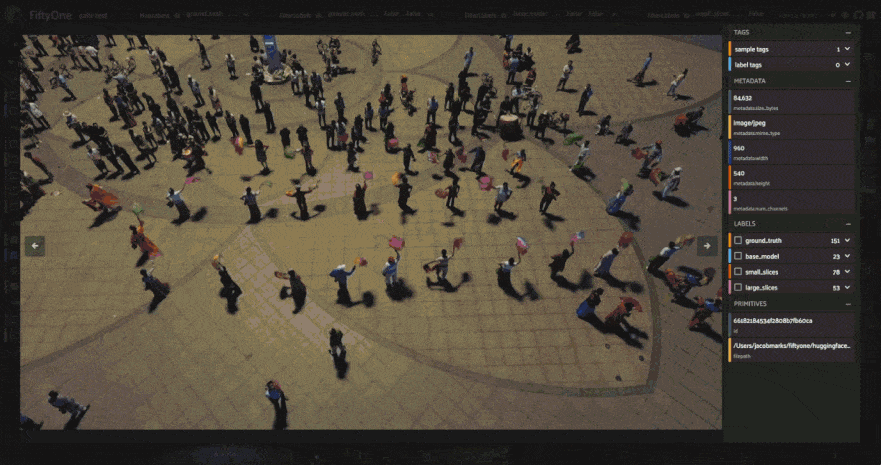
The results certainly look promising! From a few visual examples, slicing seems to improve the coverage of ground truth detections, and smaller slices, in particular, seem to lead to more of the
person detections being captured. But how can we know for sure? Let's run an evaluation routine to mark the detections as true positives, false positives, or false negatives to compare the sliced predictions to the ground truth. We'll use our filtered view's evaluate_detections() method.Evaluating SAHI Predictions
Sticking with our filtered view of the dataset, let's run an evaluation routine comparing our predictions from each prediction label field to the ground truth labels. Here, we use the default IoU threshold of 0.5, but you can adjust this as needed:
base_results = filtered_view.evaluate_detections("base_model", gt_field="ground_truth", eval_key="eval_base_model")
large_slice_results = filtered_view.evaluate_detections("large_slices", gt_field="ground_truth", eval_key="eval_large_slices")
small_slice_results = filtered_view.evaluate_detections("small_slices", gt_field="ground_truth", eval_key="eval_small_slices")
Let's print a report for each:
print("Base model results:")
base_results.print_report()

print("-" * 50)
print("Large slice results:")
large_slice_results.print_report()

print("-" * 50)
print("Small slice results:")
small_slice_results.print_report()
Base model results:
precision recall f1-score support
car 0.81 0.55 0.66 692
person 0.94 0.16 0.28 7475
truck 0.66 0.34 0.45 265
micro avg 0.89 0.20 0.33 8432
macro avg 0.80 0.35 0.46 8432
weighted avg 0.92 0.20 0.31 8432
--------------------------------------------------
Large slice results:
precision recall f1-score support
car 0.67 0.71 0.69 692
person 0.89 0.34 0.49 7475
truck 0.55 0.45 0.49 265
micro avg 0.83 0.37 0.51 8432
macro avg 0.70 0.50 0.56 8432
weighted avg 0.86 0.37 0.51 8432
--------------------------------------------------
Small slice results:
precision recall f1-score support
car 0.66 0.75 0.70 692
person 0.84 0.42 0.56 7475
truck 0.49 0.46 0.47 265
micro avg 0.80 0.45 0.57 8432
macro avg 0.67 0.54 0.58 8432
weighted avg 0.82 0.45 0.57 8432We can see that as we introduce more slices, the number of false positives increases, while the number of false negatives decreases. This is expected, as the model is able to detect more objects with more slices, but also makes more mistakes! You could apply more aggressive confidence thresholding to combat this increase in false positives, but even without doing this the F1-score has significantly improved.
Let's dive a little bit deeper into these results. We noted earlier that the model struggles with small objects, so let's see how these three approaches fare on objects smaller than 32x32 pixels. We can perform this filtering using FiftyOne's ViewField:
## Filtering for only small boxes

box_width, box_height = F("bounding_box")[2], F("bounding_box")[3]
rel_bbox_area = box_width * box_height

im_width, im_height = F("$metadata.width"), F("$metadata.height")
abs_area = rel_bbox_area * im_width * im_height

small_boxes_view = filtered_view
for lf in get_label_fields(filtered_view):
    small_boxes_view = small_boxes_view.filter_labels(lf, abs_area < 32**2, only_matches=False)

session.view = small_boxes_view.view()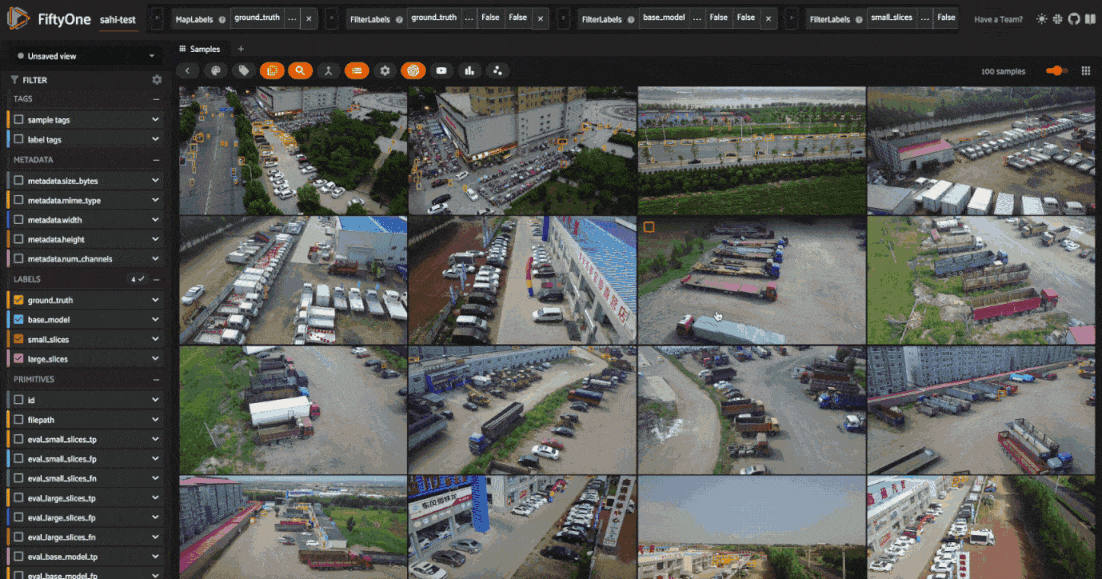
If we evaluate our models on these views and print reports as before, we can clearly see the value that SAHI provides! The recall when using SAHI is much higher for small objects without significant dropoff in precision, leading to improved F1-score. This is especially pronounced for
person detections, where the F1-score is tripled!## Evaluating on only small boxes
small_boxes_base_results = small_boxes_view.evaluate_detections("base_model", gt_field="ground_truth", eval_key="eval_small_boxes_base_model")
small_boxes_large_slice_results = small_boxes_view.evaluate_detections("large_slices", gt_field="ground_truth", eval_key="eval_small_boxes_large_slices")
small_boxes_small_slice_results = small_boxes_view.evaluate_detections("small_slices", gt_field="ground_truth", eval_key="eval_small_boxes_small_slices")
## Printing reports
print("Small Box — Base model results:")
small_boxes_base_results.print_report()
print("-" * 50)
print("Small Box — Large slice results:")
small_boxes_large_slice_results.print_report()
print("-" * 50)
print("Small Box — Small slice results:")
small_boxes_small_slice_results.print_report()
Small Box — Base model results:
              precision    recall  f1-score   support

         car       0.71      0.25      0.37       147
      person       0.83      0.08      0.15      5710
       truck       0.00      0.00      0.00        28

   micro avg       0.82      0.08      0.15      5885
   macro avg       0.51      0.11      0.17      5885
weighted avg       0.82      0.08      0.15      5885

--------------------------------------------------
Small Box — Large slice results:
              precision    recall  f1-score   support

         car       0.46      0.48      0.47       147
      person       0.82      0.23      0.35      5710
       truck       0.20      0.07      0.11        28

   micro avg       0.78      0.23      0.36      5885
   macro avg       0.49      0.26      0.31      5885
weighted avg       0.80      0.23      0.36      5885

--------------------------------------------------
Small Box — Small slice results:
              precision    recall  f1-score   support

         car       0.42      0.53      0.47       147
      person       0.79      0.31      0.45      5710
       truck       0.21      0.18      0.19        28

   micro avg       0.75      0.32      0.45      5885
   macro avg       0.47      0.34      0.37      5885
weighted avg       0.77      0.32      0.45      5885
What’s Next
In this walkthrough, we've covered how to add SAHI predictions to your data and then rigorously evaluated the impacts of slicing on prediction quality. We've seen how Slicing-Aided Hyper Inference (SAHI) can improve the recall and F1-score for detection, especially for small objects, without needing to train a model on larger images.
To maximize the effectiveness of SAHI, you may want to experiment with the following:
Regardless of which knobs you want to turn, it is important to look beyond the one-number metrics. When working on small object detection tasks, the more small objects in your images, the more likely there are missing “ground truth” labels. SAHI can help you find potential errors, which you can correct with human-in-the-loop (HITL) workflows.
If you found this helpful, here are some additional resources you may find useful:
- Tutorial on Evaluating Object Detections
- Tutorial on Finding Object Detection Mistakes
- FiftyOne Plugin for Comparing Models on Specific Detections
Loading related posts...
© 2026 Voxel51 All Rights Reserved